

About Author
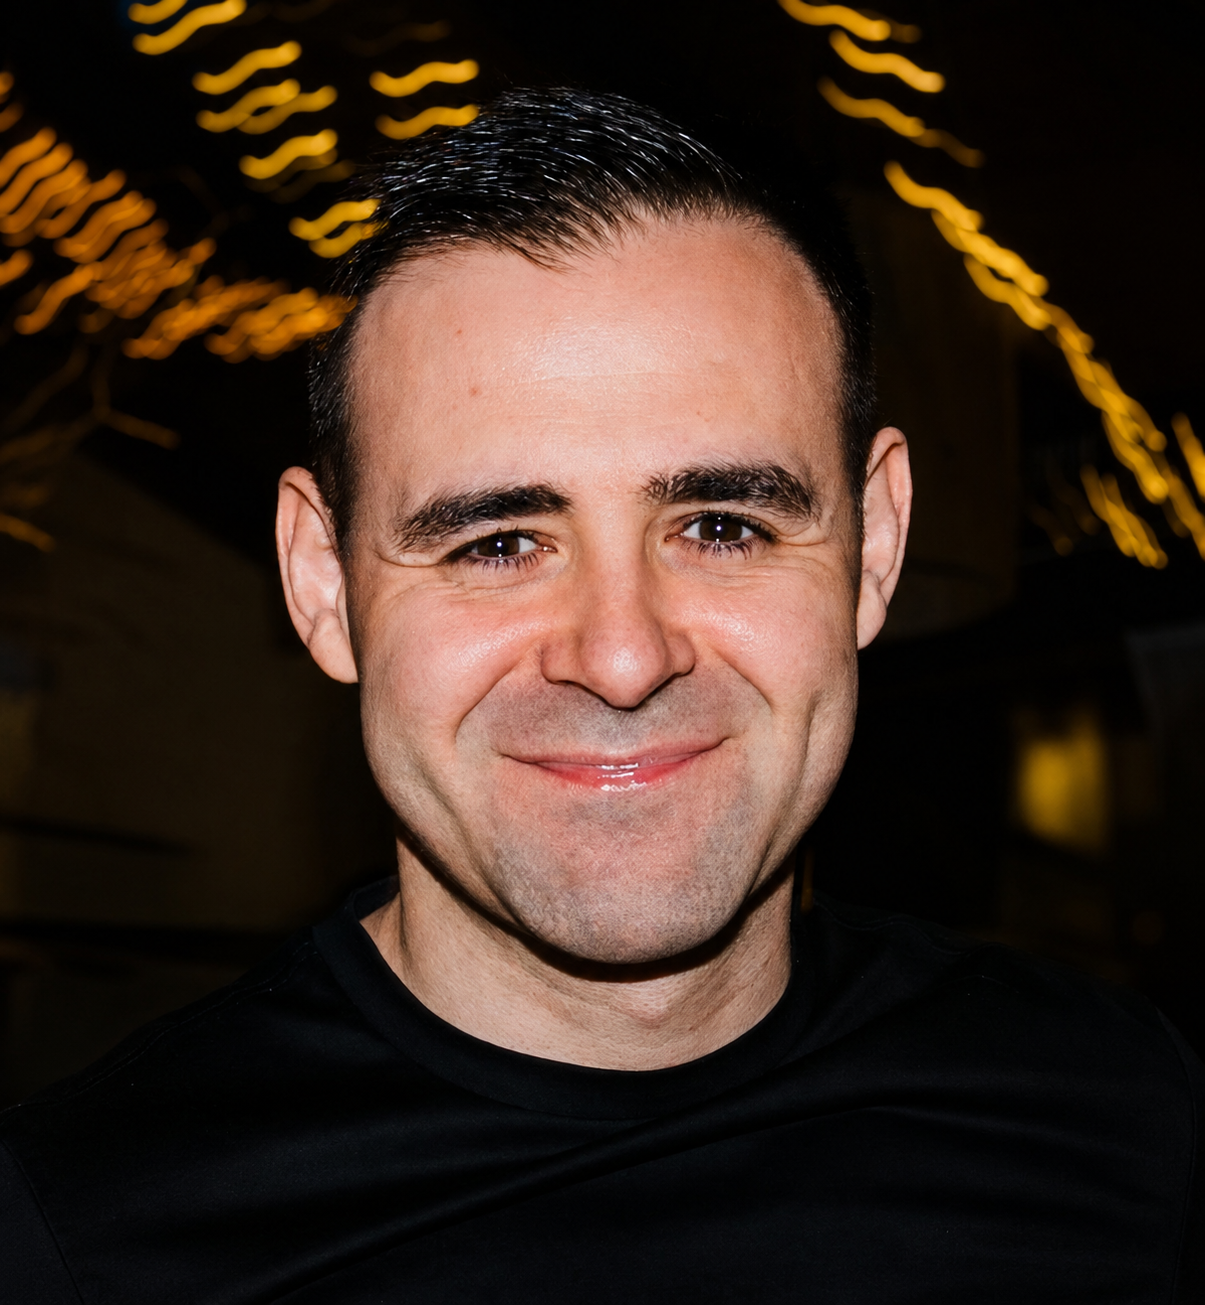
Nikola Djurdjevic
Backend & Systems Software Architect
Go · Rust · Distributed Scalable Systems · Infrastructure
Nikola Djurdjevic is a backend and systems software architect focused on building infrastructure, distributed services, developer tooling, automation systems, benchmarking software, and internal engineering platforms.
His primary development languages are Go & Rust, with previous development experience using C++ & Java.
His work is primarily centered around backend and infrastructure software rather than application frontend development.
The systems developed as part of this work include components for:
- service management
- remote execution
- infrastructure agents
- artifact distribution
- build orchestration
- release automation
- reverse proxying
- load balancing
- documentation distribution
- system benchmarking
- hardware analysis
- deployment
- monitoring
- authentication and authorization
- distributed resource management
The common objective behind these systems is to build infrastructure that remains understandable, deterministic, independently deployable, and operational without unnecessary external dependencies.
Engineering Focus
The primary engineering focus is on systems where several independent services cooperate through clearly defined protocols and responsibilities.
Typical areas include:
- Backend Services
- Distributed Systems
- Infrastructure Tooling
- Developer Tooling
- Remote Agents
- Artifact Distribution
- Build and Release Automation
- Service Management
- Reverse Proxies
- Load Balancing
- Documentation Infrastructure
- System Benchmarking
- Hardware Detection
- Monitoring
- Deployment
- Automation
The work frequently involves networking and communication technologies such as:
HTTP/1.1 HTTP/2 REST TCP UDP WebSocket TLS gRPC
The architecture of these systems generally favors small specialized services over one large application.
A typical Scalionix system may therefore consist of several independent components:
        Client => Gateway => Service / Engine
                                     |
                                     +-- Agent
                                     +-- Registry
                                     +-- Storage
                                     +-- Worker
                                     +-- External Services
Each component owns a clearly defined part of the system.
Engineering Philosophy
A recurring design principle throughout the Scalionix ecosystem is to build the required infrastructure directly when doing so provides better control, simpler deployment, or clearer operational behavior. This has resulted in custom systems for:
- artifact distribution
- service orchestration
- remote execution
- documentation serving
- benchmarking
- reverse proxying
- deployment
- build orchestration
rather than automatically introducing large infrastructure platforms for every problem.
This does not mean avoiding existing technologies.
The objective is to understand which infrastructure is actually required and to avoid introducing dependencies whose complexity is greater than the problem they solve.
Another important principle is separation of responsibilities. For example:
[Build System] => [Artifact System] => [Deployment / Agent System]
are related systems, but they do not need to be the same service. Similarly:
        Documentation Source
                ↓
        Documentation Build
                ↓
        Artifact Distribution
                ↓
        Documentation Server
forms a pipeline composed of independent responsibilities.
This makes individual components easier to:
- develop
- test
- replace
- deploy
- scale
- debug
- version
Scalionix
Scalionix is the current ecosystem under which a collection of backend services, infrastructure tools, developer utilities, and experimental systems are being developed. The systems are designed around a service-oriented architecture in which individual components can be developed and deployed independently. Major areas currently represented in the ecosystem include:
- Agent Infrastructure
- Artifact Distribution
- Build Orchestration
- Release Management
- Reverse Proxy Infrastructure
- Documentation Infrastructure
- System Benchmarking
- Service Management
- Automation
- Monitoring
Agent Infrastructure
A major part of the infrastructure work has involved agent-based service management and remote execution.
The general architecture uses agents installed on target machines.
These agents provide a controlled interface between central infrastructure services and the operating system running the managed services.
Conceptually:
        Management Service
               ↓
             Agent
               |
               +-- Service Operations
               +-- Script Execution
               +-- Deployment Operations
               +-- Monitoring
               +-- System Information
               +-- Resource Information
The agent model allows infrastructure operations to be executed on remote machines without requiring the central management service to directly control the operating system.
Operations developed around this model include:
- start service
- stop service
- restart service
- remove service
- retrieve service status
- execute scripts
- execute deployment operations
- retrieve system information
- monitor resource usage
The design also supports environments containing multiple:
- servers
- groups
- regions
- services
This agent-based approach became one of the foundations for later infrastructure components.
Artifact Distribution System
The Scalionix Artifact system was designed to provide controlled distribution of service binaries, tools, scripts, documentation packages, and other release artifacts.
The system is divided into specialized components.
Conceptually:
        Artifact Engine
              |
              +-------------------+
              ↓                   ↓
        Artifact Server      Artifact Gateway
              ↓
        Artifact Storage
A registry component is also part of the broader architecture.
Artifact Engine
The Artifact Engine acts as an orchestration layer.
It is responsible for coordinating artifact-related operations across one or more targets.
Targets can be organized using concepts such as:
- Sectors
- Groups
- Targets
- Items
A sector represents a larger service or infrastructure grouping. Groups represent subsets within a sector. Targets represent destination systems such as:
- artifact servers
- artifact gateways
- managed infrastructure
Items represent deployable or executable resources such as:
- artifacts
- scripts
- service packages
The Engine supports different execution patterns. Examples include:
- single-target execution
- multi-target execution
- broadcast execution
Execution can therefore be directed toward one specific target or distributed across several infrastructure nodes.
The Engine also maintains execution history and supports snapshot-oriented operations for comparing or reproducing infrastructure state.
Artifact Server
The Artifact Server provides artifact storage and retrieval. Its responsibilities include:
- artifact upload
- artifact storage
- artifact download
- authorization
- release organization
Artifacts may be organized by:
- service
- version
- operating system
- architecture
- edition
This allows the same service release to contain several independently generated binaries.
For example:
        service
        ├── linux
        │   ├── amd64
        │   └── arm64
        ├── darwin
        │   ├── amd64
        │   └── arm64
        └── windows
            ├── amd64
            └── arm64
Artifact Gateway
The Artifact Gateway provides a distribution layer in front of artifact servers.
Instead of storing artifacts itself, it can redirect requests toward available storage nodes.
The gateway supports weighted distribution behavior, allowing several artifact servers to participate in release delivery.
Conceptually:
        Client
           ↓
        Artifact Gateway
           |
           +------> Artifact Server A
           |
           +------> Artifact Server B
           |
           +------> Artifact Server C
This separates artifact storage from artifact routing.
Artifact Registry
The broader Artifact architecture also includes the concept of a registry responsible for centralized metadata and infrastructure relationships.
The registry architecture includes concepts such as:
- users
- roles
- engines
- authentication keys
- snapshots
- online engine state
This provides a foundation for managing larger installations containing multiple Artifact Engines and infrastructure nodes.
Build Orchestration
Another part of the Scalionix infrastructure is a native build orchestration system.
The build system was created to automate compilation across a matrix of:
- services
- operating systems
- architectures
- editions
A single service may need artifacts for:
- Linux [AMD64/ARM64]
- Darwin [ARM64]
- Windows [AMD64/ARM64]
and may additionally provide editions such as [Community/Enterprise].
When applied across many services, a release can produce hundreds of individual artifacts. The build orchestrator automates this process. Its responsibilities include:
- repository preparation
- build-directory creation
- build cleanup
- dependency synchronization
- build-script generation
- parallel build execution
- version stamping
- artifact packaging
- release metadata generation
- tagging
- push operations
Builds may be selected by:
- Service
- Group
- Sector
allowing both individual service builds and larger ecosystem releases.
Build Metadata
Generated services contain build information such as:
- Version
- Commit
- Build Time
This allows a running binary to identify exactly which source revision produced it.
A typical release artifact follows a deterministic naming convention containing information such as:
- service
- edition
- operating system
- architecture
- version
This provides traceability between:
Source => Commit => Build => Artifact => Release
Go and Rust Build Infrastructure
The build infrastructure supports both Go and Rust services.
Go services can be built using options for:
- trimpath
- symbol stripping
- empty build IDs
- build obfuscation
- version stamping
Rust services use a corresponding cross-platform build pipeline.
Rust targets include environments such as:
- Linux [AMD64/ARM64]
- Darwin [ARM64]
- Windows [AMD64/ARM64]
Cross-compilation environments were created where practical, while native builds are used where platform requirements make them preferable.
The objective is for Go and Rust services to participate in the same higher-level release process even though their underlying build systems are different.
Release Pipeline
The combination of the build and artifact systems creates a larger release pipeline.
Conceptually:
        Source Repository
               ↓
        Build Orchestrator
               ↓
        Build Matrix
               ↓
        Package Artifacts
               ↓
        Artifact Server
               ↓
        Artifact Gateway
               ↓
        Target Infrastructure
This architecture keeps compilation, storage, distribution, and deployment as separate responsibilities.
Scalionix Gateway
Scalionix also includes a native reverse-proxy and gateway service.
The gateway was developed to provide:
- TLS termination
- HTTP/2
- HTTP redirects
- reverse proxying
- backend routing
- load balancing
- health checking
It can route several public endpoints toward independent internal services. Conceptually:
        Internet
           ↓
        Scalionix Gateway
           |
           +------> Website
           |
           +------> Platform
           |
           +------> API
           |
           +------> Documentation
The gateway allows internal services to remain on independent ports while presenting a unified public interface.
Backend pools can contain multiple service instances. Requests can then be distributed between healthy backend nodes. This provides a foundation for:
- redundancy
- service replacement
- horizontal expansion
- maintenance
- backend failover
without requiring clients to know the internal infrastructure topology.
Scalionix Documentation Infrastructure
Scalionix documentation is built using mdBook.
Documentation is maintained separately from application source where independent versioning and release history are useful.
This makes it possible for each service or tool to maintain its own:
- documentation repository
- documentation versions
- release tags
- build history
- language separation
rather than placing every document in one monolithic repository.
The generated documentation is static HTML. A typical pipeline is:
        Documentation Repository
                ↓
             mdBook
                ↓
              book/
                ↓
        Documentation Artifact
                ↓
        Artifact Distribution
                ↓
        Scalionix Docs Server
Scalionix Docs Server
The Scalionix Docs Server is a Go service developed for serving documentation generated by systems such as mdBook.
The original implementation supported documentation embedded directly into the service binary.
This is useful for:
- local tools
- portable documentation
- single-book applications
- self-contained binaries
However, embedding every documentation version does not scale well for a centralized documentation service.
For example:
100 projects × 100 documentation versions × 3 MB per book ≈ 30 GB
Embedding that data would also require rebuilding the Docs Server whenever a new documentation release was added.
The architecture was therefore expanded to support a filesystem-backed documentation library.
Conceptually:
        Scalionix Docs Server
                ↓
        Documentation Library
                |
                +-- service-a
                |     +-- 1.0
                |     +-- 1.1
                |     +-- 2.0
                |
                +-- service-b
                |     +-- 1.0
                |     +-- 2.0
                |
                +-- tool-a
                      +-- 3.0
The server can resolve documentation dynamically from the active library.
A central installation may therefore use a layout such as /srv/scalionix/docs/, with individual books organized by:
- project
- version
- book
This allows the Docs Server binary to remain unchanged when documentation is added. Documentation deployment becomes:
        Git Repository
              ↓
        mdbook build
              ↓
            book/
              ↓
           Package
              ↓
        Artifact Server
              ↓
        Documentation Deployment
              ↓
        /srv/scalionix/docs/<project>/<version>/
Version directories can remain immutable while aliases such as latest identify the currently recommended version.
This separates [Documentation Server Release] from [Documentation Content Release],
which allows both to evolve independently.
Documentation Portal
The Docs Server also provides a central interface for discovering available documentation.
Instead of requiring users to manually know every documentation URL, the server maintains information about:
- services
- tools
- versions
- default versions
- documentation URLs
This allows one Docs Server instance to become an entry point for documentation across the Scalionix ecosystem.
Scalionix System Benchmark
Another major project is the Scalionix System Benchmark.
It is a cross-platform benchmark written in Rust for measuring system performance using workloads designed to resemble real software operations.
The benchmark targets [Linux/Darwin] and collects information about the system being tested.
The benchmark architecture contains several workload categories. These include:
- JSON
- Hashing
- Encryption
- Compression
- Collections
- Concurrency
- Compilation
- Storage
The benchmark is designed around repeatable scenarios rather than a single synthetic loop.
JSON Benchmarking
JSON workloads measure serialization, deserialization, memory processing, and filesystem interaction involving structured data.
Operations include scenarios such as:
- serialization
- deserialization
- memory processing
- file processing
- round trips
- raw file reads
- pre-serialized file writes
Scenarios are executed across different:
- dataset sizes
- object counts
- worker counts
This makes it possible to observe both single-thread and multi-thread behavior across workloads of different sizes.
Hashing Benchmarking
Hashing workloads measure the performance of commonly used cryptographic hash functions.
Algorithms include:
- BLAKE3
- SHA-256
- SHA-512
Execution styles include:
- chunked
- one-shot
These scenarios make it possible to compare hashing performance across different algorithms, data sizes, and execution strategies.
Encryption Benchmarking
Encryption workloads measure authenticated encryption performance using commonly used algorithms.
Algorithms include:
- AES-128-GCM
- AES-256-GCM
- ChaCha20-Poly1305
Operations include:
- encrypt
- decrypt
- round trip
The workloads are designed to measure both individual cryptographic operations and complete encrypt-decrypt processing paths.
Compression Benchmarking
Compression workloads measure the performance of data compression and decompression operations.
The scenarios are designed to observe the computational cost of processing data through compression workloads rather than measuring only raw memory throughput.
They can be used to evaluate behavior across different:
- dataset sizes
- compression operations
- decompression operations
- worker counts
This makes it possible to compare both single-thread and multi-thread compression performance under repeatable workloads.
Collections Benchmarking
Collections workloads measure operations performed on in-memory data structures.
The objective is to observe behavior that appears frequently in real applications, where data is inserted, accessed, searched, modified, iterated, or removed from collections.
Scenarios can exercise operations such as:
- insertion
- lookup
- iteration
- modification
- removal
The workloads can be executed with different collection sizes and execution configurations, allowing the benchmark to observe how performance changes as the amount of managed data increases.
Concurrency Benchmarking
Concurrency workloads measure the behavior of the system when work is distributed across multiple execution contexts.
The objective is not simply to maximize CPU utilization, but to observe the cost and scalability of concurrent processing.
Scenarios can evaluate behavior across different:
- worker counts
- task counts
- synchronization patterns
- shared workloads
This makes it possible to compare single-worker execution with increasingly parallel workloads and observe how effectively the system scales as concurrency increases.
Compilation Benchmarking
Compilation benchmarking measures real build workloads.
The objective is to measure production-style compilation rather than an artificial CPU loop.
Compilation scenarios can record:
- toolchain
- worker count
- iterations
- best duration
- worst duration
- duration spread
- throughput
- artifact verification
Generated artifacts are verified so that a failed or incomplete compilation cannot be treated as a successful benchmark result.
This allows compilation performance to represent an actual developer workload, including both execution time and successful artifact production.
Storage Benchmarking
Storage workloads measure filesystem behavior rather than only raw sequential throughput.
Operations include scenarios such as:
- file operations
- directory traversal
- metadata operations
- rename operations
The benchmark is designed to observe end-to-end storage behavior through the operating system and filesystem.
This provides a workload-oriented view of storage performance that is closer to application behavior than a simple sequential read or write benchmark.
Hardware Detection
The benchmark collects a hardware snapshot describing the machine on which the benchmark was executed.
Information may include:
- CPU
- physical cores
- logical processors
- memory
- storage devices
- operating system
- architecture
Platform-specific detection is used where necessary.
For example, hardware information may be obtained from operating-system facilities such as:
- SMBIOS
- udev
- APIs
The objective is to identify the tested hardware accurately enough for comparison and result validation.
Benchmark Concurrency
Benchmark scenarios are executed using multiple worker configurations.
This allows comparison of behavior at levels such as:
[ 1 / 2 / 4 / 6 / 8 / 12 / 16 / 20 / 24 / 32 ] number of workers
The objective is not only to determine maximum throughput.
The benchmark can also show how efficiently a machine scales as additional concurrency is introduced.
Benchmark Scoring
Raw benchmark results are transformed into a structured scoring model.
Conceptually:
Scenario Results => Workload Score => Category Score => Global Score
This produces several levels of comparison.
A machine can therefore be compared using:
- individual scenario performance
- workload performance
- category performance
- global performance
The scoring system uses versioned references so that score calculation can evolve while remaining identifiable.
Benchmark Reports
The benchmark produces structured reports containing:
- benchmark results
- hardware information
- scoring information
- verification data
- report identifiers
The reporting model separates detailed local benchmark data from the compact information required for global comparison.
This allows large raw benchmark reports to remain local while only the required Global Score Report is submitted to a ranking service.
Global Benchmark Ranking
The broader benchmark architecture includes a public ranking system for comparing hardware configurations.
The ranking system is designed to support comparisons across:
- Global Score
- Categories
- Workloads
- Hardware Classes
Rather than storing only one final number, the architecture can preserve enough information to understand where a system performs well or poorly.
The ranking architecture also considers:
- hardware fingerprints
- duplicate detection
- scoring versions
- historical results
- machine categories
This makes the benchmark useful for more than a single local performance test.
Native Infrastructure
A recurring characteristic of the Scalionix ecosystem is the preference for native service execution where appropriate.
Many services are designed to run directly as binaries rather than requiring a container runtime as part of their normal deployment model.
This keeps the operational path simple:
Binary => Operating System
and allows the surrounding infrastructure to manage:
- service lifecycle
- configuration
- networking
- deployment
- monitoring
- artifact delivery
directly.
Containers and virtualized environments may still be useful for isolated build or compatibility scenarios, but they are not assumed to be a mandatory runtime dependency for the ecosystem.
Cross-Platform Development
The ecosystem targets several operating systems and architectures.
Common targets include [Linux/Darwin/Windows] and [AMD64/ARM64].
This influences the design of:
- build systems
- artifact naming
- hardware detection
- benchmarking
- filesystem handling
- service packaging
Cross-platform behavior is treated as an architectural concern rather than an afterthought.
Programming Task Library
The Programming Task Library was originally created in January 2024 as a practical training resource for software developers.
The library was designed to encourage developers to think beyond:
the code compiles
or:
the expected value was returned
and instead consider:
- correctness
- algorithm design
- data modeling
- performance
- resource consumption
- validation
- abstraction
- flexibility
- edge cases
- maintainability
The original library focused primarily on Go and Rust. The current version reorganizes and expands that material into structured documentation.
It contains two major sections: Algorithms & Modeling.
The Algorithm section focuses on problem-solving and data processing. The Modeling section focuses on transforming real-world requirements into software systems containing entities, relationships, state, resources, scheduling, transactions, failures, recovery, and domain invariants.
Technology
The primary technologies and engineering areas represented across the projects include:
- Go / Rust
- HTTP/1.1 - HTTP/2
- REST
- TCP / UDP
- WebSocket
- TLS
- Linux / Darwin / Windows
- AMD64 / ARM64
- Git / Gitea / mdBook
The exact technology is selected according to the requirements of each system.
Go is used extensively for network services, infrastructure components, and backend tooling.
Rust is used for systems where low-level control, performance, concurrency, hardware interaction, or systems-programming practice is particularly valuable.
Current Direction
The current Scalionix work is gradually forming a connected engineering platform.
Individual systems remain independent, but they can participate in larger workflows.
For example:
        Source
           ↓
        Build Orchestrator
           ↓
        Artifact System
           ↓
        Deployment Infrastructure
           ↓
        Agent
           ↓
        Running Service
Documentation follows a parallel lifecycle:
        Documentation Source
           ↓
        mdBook Build
           ↓
        Documentation Artifact
           ↓
        Artifact Distribution
           ↓
        Docs Server
           ↓
        Scalionix Gateway
           ↓
         User
Benchmarking forms another independent subsystem:
        Machine
           ↓
        System Benchmark
           |
           +-- Hardware Snapshot
           +-- Workload Results
           +-- Verification
           +-- Scoring
           ↓
        Global Score Report
           ↓
        Ranking Infrastructure
The common theme is not one specific technology or product.
It is the development of infrastructure where each layer has an explicit responsibility and can be understood independently while still participating in a larger system.
Original Publication
The original version of the Programming Task Library was published as:
Training Task Library — Scalionix Development Team
Created by: Nikola Djurdjevic [LinkedIn]
Published: January 2021Original technology focus: Golang & Rust & C++
The current documentation preserves the original exercises while reorganizing, correcting, documenting, and extending the collection into a larger programming and software-modeling resource.